I Almost Built This on Postgres. Here's Why I Didn't.
My AI agent audit trail is an append-only NDJSON receipt ledger. It almost wasn't.
In October 2025 I started scaling my orchestration system across four AI agent terminals. I did what every engineer does and reached for a database. PostgreSQL, because it's what I know: ACID guarantees, concurrent writers, proper backup tooling.
Then at 2 AM, running dispatch #847, something broke silently in the audit trail. A transaction rolled back, and the write that should have recorded the failure went with it.
I found out 36 hours later. A cost report showed $0 spent on that entire dispatch batch.
That's when it clicked: the audit trail for a multi-agent AI system isn't a database problem. It's a flight recorder problem.
A flight recorder doesn't need transactions or foreign keys. It needs one thing: when everything else is falling apart, the record gets written. Appended, never rolled back.
I moved the audit trail to NDJSON that week. On 17 October 2026 my project stores hold 44,075 receipts, and the design below is how they got there.
Over time a second idea grew out of the first. The ledger isn't a log next to the system. It is the system's state. Every other state file is a cache I can delete and rebuild.
Why a Database Was the Wrong Tool for This Audit Trail
Four terminals, each running several tasks, each task emitting events. Completion receipts, failure receipts, gate decisions, cost records, state mutations.
The obvious schema looks harmless:
CREATE TABLE dispatch_receipts (
  id uuid PRIMARY KEY,
  dispatch_id uuid NOT NULL,
  terminal_id varchar NOT NULL,
  action varchar NOT NULL,
  timestamp timestamptz NOT NULL,
  data jsonb NOT NULL
);
Three things went wrong for me in practice:
- The audit write shared a fate with the work. When the surrounding transaction rolled back, the record of the failure rolled back too. That's the 2 AM bug.
- Write contention. Four terminals writing the same table at the same moment meant lock waits on the path that should never wait.
- No single truth after a crash. Was the dispatch done? The database said one thing, the running worker another, a half-written batch a third.
Postgres is excellent at mutable shared state. An audit trail is the opposite. It moves in one direction, it is never updated, and it has to survive the very failure it is recording.
Why NDJSON Specifically
NDJSON is newline-delimited JSON. One valid JSON object per line, and every line parses on its own.
{"dispatch_id":"d-001","terminal":"T0","event_type":"dispatch_created","timestamp":"2026-02-27T09:15:32Z"}
{"dispatch_id":"d-001","terminal":"T1","event_type":"task_started","timestamp":"2026-02-27T09:15:35Z"}
Five properties made it the right fit.
1. A crash damages one line, not the file
If a write dies halfway, only the last line is broken. Everything before it is still valid JSON.
# Last line is truncated, the rest is intact
$ tail -1 t0_receipts.ndjson
{"dispatch_id":"d-002","terminal":"T2","event_type":"task_fa

# Drop that line and carry on
$ sed -i '' '$d' t0_receipts.ndjson
2. The Unix toolkit is your query language
tail, grep, jq and awk were built for exactly this kind of sequential record.
# Follow one terminal live
$ tail -f t0_receipts.ndjson | jq -c 'select(.terminal=="T1") | {dispatch_id, event_type, status}'

# Count events by type
$ jq -r '.event_type' t0_receipts.ndjson | sort | uniq -c | sort -rn | head
That second command is how I know my VNX store holds 16,345 task_complete events.
3. No server, no migrations
It's a file. No process to keep alive, no connection pool, no migration scripts. When something is broken at 4 AM, I open a terminal and read the ledger. Nothing has to be up for that to work.
4. Readable by anyone
Every receipt is plain JSON. I can paste one line into an issue and the reader understands it without a schema or a client.
5. Corrections are new lines
You don't UPDATE a receipt. If something was wrong, you append a correction that points at the receipt it supersedes.
{"dispatch_id":"d-003","receipt_id":"r-1","event_type":"cost_calculated","cost_usd":12.34}
{"dispatch_id":"d-003","receipt_id":"r-2","event_type":"cost_corrected","supersedes":"r-1","cost_usd":11.87,"reason":"api_call_recount"}
The format doesn't enforce this. A text file can be edited. Append-only is a discipline the write path keeps, and I come back to what that means for proof at the end.
📖 Read also: One Terminal to Rule Them All: how the receipt ledger connects to the full multi-agent orchestration architecture
A Real Receipt
This is a receipt from my ledger, trimmed to the fields that matter here. A review gate finished on 29 September and the system decided whether to accept the result.
{
  "timestamp": "2026-09-29T21:47:47.082782+00:00",
  "event_type": "task_complete",
  "dispatch_id": "deepseek-gate-pr1999-1790718076",
  "terminal": "plan-gate",
  "status": "done",
  "verdict": {
    "decision": "accept",
    "reason": "status='done', verification 101/101 tests passed, no blocker or oi_pending warnings",
    "evidence_complete": true
  },
  "provenance": {
    "git_ref": "8ca62fb22625562c717776728b1cdb224ba62f48",
    "branch": "main",
    "is_dirty": true,
    "dirty_files": 6
  },
  "schema_version": 2
}
Two fields do most of the work.
verdict records why the system accepted or refused, with evidence_complete as a separate flag. The same morning I write this, another receipt says "decision": "investigate". The worker reported status "unknown", which is "neither a hard-failure status nor a recognized success status". No basis for accept, so it isn't accepted.
provenance records the commit the work ran against and whether the worktree was clean. Here it wasn't: six backup files lay around. The receipt says so, so nobody has to remember it.
Three Streams, Not One File
A single ledger has a contention problem. Gate decisions, lifecycle events and agent actions all want to write at once. The wrong fix is one file with more locking. The right one is three streams, each with one job.
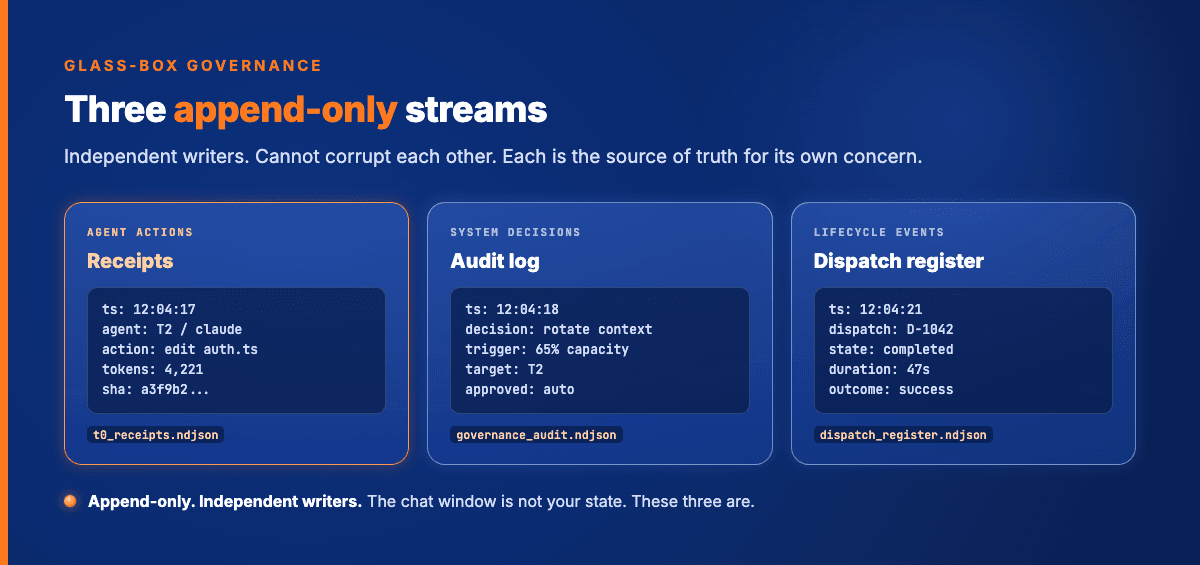
t0_receipts.ndjson: agent actions. Every lifecycle event a worker emits.governance_audit.ndjson: system decisions. Every gate decision, escalation or state mutation that crosses a governance boundary. Receipts answer "what did the agent do?" The audit log answers "what did the system decide about it?"dispatch_register.ndjson: the canonical lifecycle. One normalized timeline a dashboard can replay, fromdispatch_createdtodispatch_completed.
A malformed write to one stream can't corrupt the other two. The dashboard reads its live updates straight off these files.
The longer argument for this shape is in log-shaped state architecture.
Every Other State File Is a Cache
This is the part most teams resist. If receipts are canonical, then the orchestrator's state file, the PR queue state and the lease tables are all derived. You can delete them.
rm .vnx-data/state/t0_state.json
python3 scripts/build_t0_state.py
jq '.summary' .vnx-data/state/t0_state.json
build_t0_state.py replays the ledger and rebuilds the state. In May it was 974 lines. Today it is 3,252.
A killed dispatcher used to raise the question "did that dispatch land or not?" With state in chat scrollback, that question has no answer. With state in the ledger, it is one replay away.
Crash recovery comes free with this design, on one condition. The receipt has to be written before the action counts as done. Write it asynchronously and crash before the flush, and you lose that dispatch like any other architecture would.
One Lock, Not One Writer
Appends to a regular file are not automatically safe from several processes at once. Large writes can interleave.
The VNX append path takes an exclusive fcntl.flock on a lock file next to the ledger before it writes. Concurrent workers queue for a moment instead of interleaving a line. The same path keeps an idempotency cache, so a retried write doesn't produce a duplicate receipt.
Instruction Provenance
Every receipt can carry a SHA-256 hash of the literal instruction the worker received. Without it you can't verify afterwards that a receipt belongs to the instruction that actually ran.
With it you can show that a commit came from exactly this prompt, without trusting the worker's own report. The full story is in instruction SHA-256 provenance.
What It Costs
Four real costs, in the order I ran into them.
Logs need compaction. After six months one archive had grown to 391 MB and the live stream to the dashboard choked. scripts/compact_state.py now rotates archives and evicts stale digest entries. It also has a mode that caps the receipt file at 10,000 records and archives the overflow. My VNX store sits at 35,660 lines today, so that mode isn't running there.
Schema drift between writers and readers. Writers once wrote status: "completed" while readers checked verdict == "pass". The result was a false-negative loop that looked like failing gates. The fix was one shared module that defines what a pass is. Write that module before you have a second writer, not after.
You give up SQL. No joins across streams and no transactions. jq, grep and small aggregator scripts cover most questions. For a real multi-dimensional question you do more pipeline work than a database would need.
Every query is a scan. At tens of thousands of receipts that takes seconds. At tens of millions you want a warehouse next to the ledger, fed from it.
📖 Read also: The External Watcher Pattern: how the receipt ledger feeds independent agent observation that doesn't rely on self-reports
When You Should Use a Database Instead
I'm not against databases. The ledger is right for one shape of data: immutable, append-only and written before it's read. Use Postgres when you need:
- Mutable state. If your governance events need updates, look at your event model first.
- Frequent joins across many dimensions.
- Transactions that must change A and B together or neither.
- Retention rules that delete data after a fixed period.
My ledger fits the other side on every point. It has one append path under a lock, it's read in scans and replays, and losing a network call is acceptable where losing a record isn't.
More on the Receipt Ledger and VNX
- From a tmux pane to an autonomous orchestrator: eight months of building VNX, and why receipts were the key design choice
- VNX 1.7: what the framework enforces now: what I promised in June against what the code checks today
- A control plane for AI coding CLIs: why I open-sourced VNX
- Intelligence beats memory: a self-learning pipeline instead of a bigger context window
- Zero-LLM context injection: giving agents the right code at the right time without a model in the loop
- Een AI audit trail zonder database: the same idea in Dutch, written for business owners
What This Changes for AI Agent Governance
In a multi-agent system the audit trail is the system. When a model in one terminal writes code that breaks tests in another, I need to see what it was asked and what it produced. I need the time, the cost, whether a gate caught it and whether the fix held.
A table with UPDATE and DELETE rights leaves a question open: was this record always this value? A ledger with append-only discipline keeps the order of events intact.
One limit matters if you show this to an auditor. Append-only is a property of my write path, not of the file. VNX can hash-chain each receipt to the one before it, so any edit breaks the chain. That chain is opt-in per project and off by default, and my main ledger runs without it. Until it's switched on, the ledger is a faithful record I trust, not proof I can hand over.
If you're designing a governance layer like this for your own agents, this is the kind of AI architecture work I do.
This post is part of the Glass Box Governance series.
Previous: The Cascade of Doom: When AI Agents Hallucinate in Chains Next: One Terminal to Rule Them All: Multi-Model AI Orchestration
📚 Glass Box Governance series
- One Terminal to Rule Them All: How I Orchestrate Claude, Codex, and Gemini Without Them Knowing About Each Other
- Receipts, Not Chat Logs: What Thousands of AI Agent Dispatches Taught Me About Governance
- The Cascade of Doom: When AI Agents Hallucinate in Chains
- Why I Chose NDJSON Over Postgres for My AI Agent Audit Trail ← you are here
- Claude Agent Teams vs. Building Your Own: What Anthropic Solved (And What They Left Out)
- The External Watcher Pattern: How I Observe AI Agents Without Trusting Their Self-Reports
- Why Architecture Beats Models: Lessons from Thousands of AI Agent Dispatches
- Async Quality Gates: Why AI Agents Don't Get to Decide When They're Done
- From Human-in-the-Loop to Human-on-the-Loop: A Production Graduation Path
- Traceability as Architecture: Designing AI Systems Where Every Decision Has a Receipt
- Decision-Making Architecture: Why Autonomous Agents Need Governance, Not Just Instructions
- Context Rotation at Scale: How VNX Keeps AI Agents Honest After 10,000 Dispatches
- Autonomous Agent Patterns: 5 Production-Tested Approaches for Agents That Run Without You
- Governance Scoring: How to Measure Whether Your AI Agent Deserves More Autonomy
Vincent van Deth
AI Strategy & Architecture
I build production systems with AI — and I've spent the last six months figuring out what it actually takes to run them safely at scale.
My focus is AI Strategy & Architecture: designing multi-agent workflows, building governance infrastructure, and helping organisations move from AI experiments to auditable, production-grade systems. I'm the creator of VNX, an open-source governance layer for multi-agent AI that enforces human approval gates, append-only audit trails, and evidence-based task closure.
Based in the Netherlands. I write about what I build — including the failures.